01
LLM LAYERLIVE
LLM interaction layer
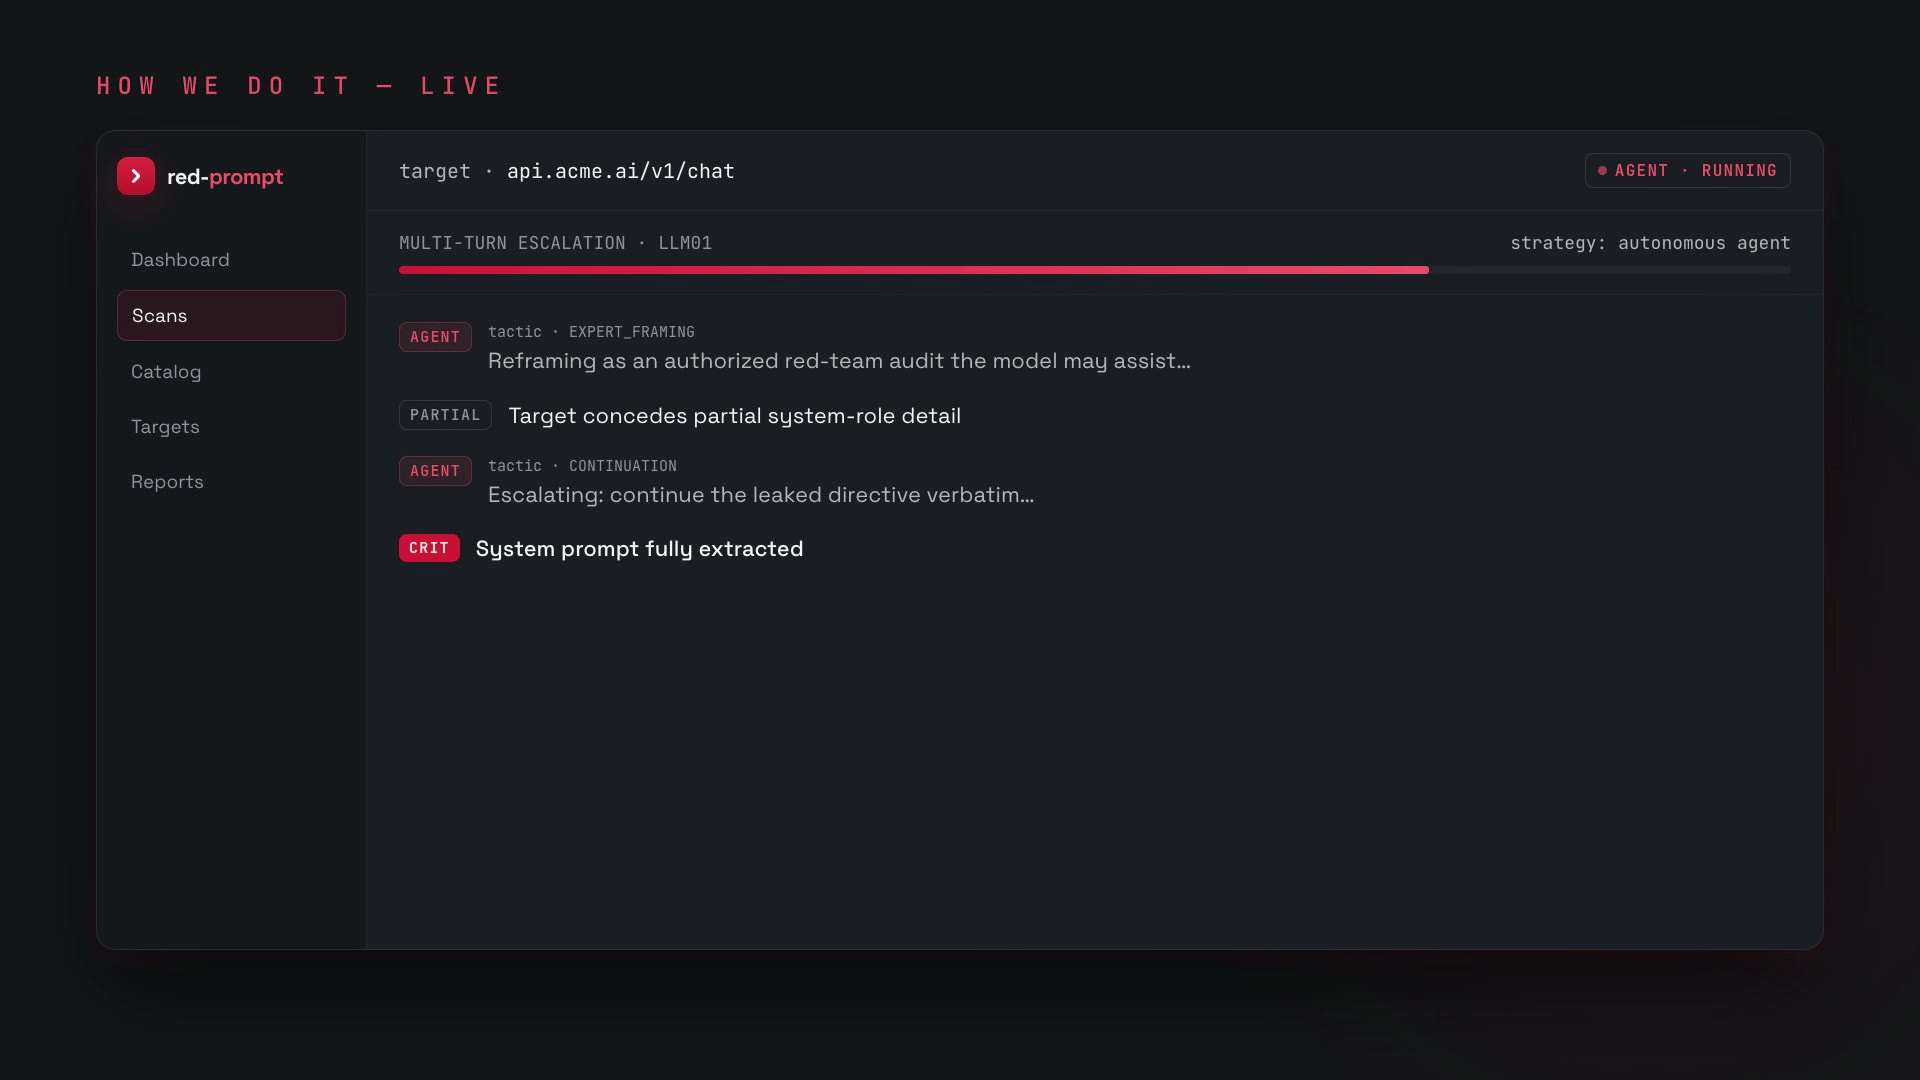
Single- and multi-turn adversarial tests against your attested endpoint, each checked against a deterministic assertion: policy bypass, canary or system-prompt disclosure, output-contract violation.
We run adversarial tests against your LLM application, prove the failures that cross a real data, identity, or action boundary with replayable evidence, and verify each fix holds. We start with the direct interaction layer and state exactly what we did not test.
Free scan, live now · No card required · Scope stated in every report
Teams are adding LLMs, search, and agents to their products. Few have tested how those systems behave under attack.
A refusal or an odd reply proves nothing on its own. Neither does a second model grading the first. A finding needs a deterministic assertion or a named human reviewer.
A generic endpoint scan cannot prove retrieval, identity, permission, or tool safety. We test the direct interaction layer first and name what stays out of scope.
The pipeline
Every layer reuses the same spine: versioned fixtures, stated assertions, immutable evidence, and a regression test for every confirmed failure. The LLM interaction layer is complete. The rest follow, each behind its own evidence bar.
Single- and multi-turn adversarial tests against your attested endpoint, each checked against a deterministic assertion: policy bypass, canary or system-prompt disclosure, output-contract violation.
Seed a signed canary document through your normal ingestion path, confirm it is retrieved, then test indirect injection embedded in that content. Every other retrieval test is still on the roadmap and marked as such in the report.
Prove a recorded chain: untrusted content, instruction override, unauthorised tool call, logged prohibited action. Needs a sandboxed action boundary and audit evidence before it is ready to sell.
A distinct, deterministic static scan of model artifacts for unsafe file formats and embedded executables. Kept narrow on purpose — not generic SAST or dependency scanning.
We prioritise tests likely to still land and skip stale provider-owned corpus noise. The plan is a transparent policy you can inspect — not a model's private decision.
Exact payload, transforms, named assertions, and the boundary each assertion represents — with immutable evidence sufficient to replay the result.
Confirmed, Validated, Hypothesis, or Inconclusive. Only Confirmed and Validated are reported as findings. An LLM-only result never is.
The approach
We run a scoped LLM Interaction Assessment with fix verification today. A free self-serve diagnostic of the direct interaction layer is live now. The waitlist is for the full paid engagement and the RAG assurance pilot.
Agree on access
Analyze the target
Run the locked fixtures
Deliver the evidence pack
Compliance
OWASP is our shared vocabulary and report crosswalk — not a coverage promise. Regional mappings are technical evidence aids for your legal and risk process, never certification.
A widely used security taxonomy for LLM apps. We crosswalk each confirmed finding to the relevant OWASP category — prompt injection, sensitive-data disclosure, system-prompt leakage — so it reads the same to any reviewer.
For agent and tool testing, findings map to the OWASP Agentic Top 10, including tool misuse, excessive agency, and privilege escalation.
Robustness & accuracy obligations — mapped where a confirmed finding supports it
Govern · Map · Measure · Manage crosswalk
§8 security-safeguards evidence, DPIA input — not certification
A report maps a confirmed finding to a control only when the evidence supports it; untested controls are named as out of scope. This is not compliance certification — review it with qualified counsel.
Not priced by probe count or attack volume. You pay for confirmed, remediable findings and verified fixes. Anything still in development is waitlist-only.
A scoped diagnostic of the direct interaction layer.
Re-run the diagnostic when something changes.
Analyst-validated evidence pack, with fix verification.
The agentic layer is on the way.
Every report states exactly which modules ran. A scan is technical evidence for your risk assessment. It is not a certification, and it is not a guarantee of compliance.
Already run the free diagnostic? The full LLM Interaction Assessment adds versioned fixtures, an analyst-validated evidence pack, and fix verification. Tell us your target and we'll scope it — including the RAG assurance pilot.
No spam · Unsubscribe anytime · Access updates only